 Jev AI
Jev: The AI Decision Model Built for Choices, Scores, and Clearer Automation
What is Jev? Learn how the Jev AI model turns text into typed decisions, which Jev model names matter, how it compares with chat models, and where to try it on Jev AI.
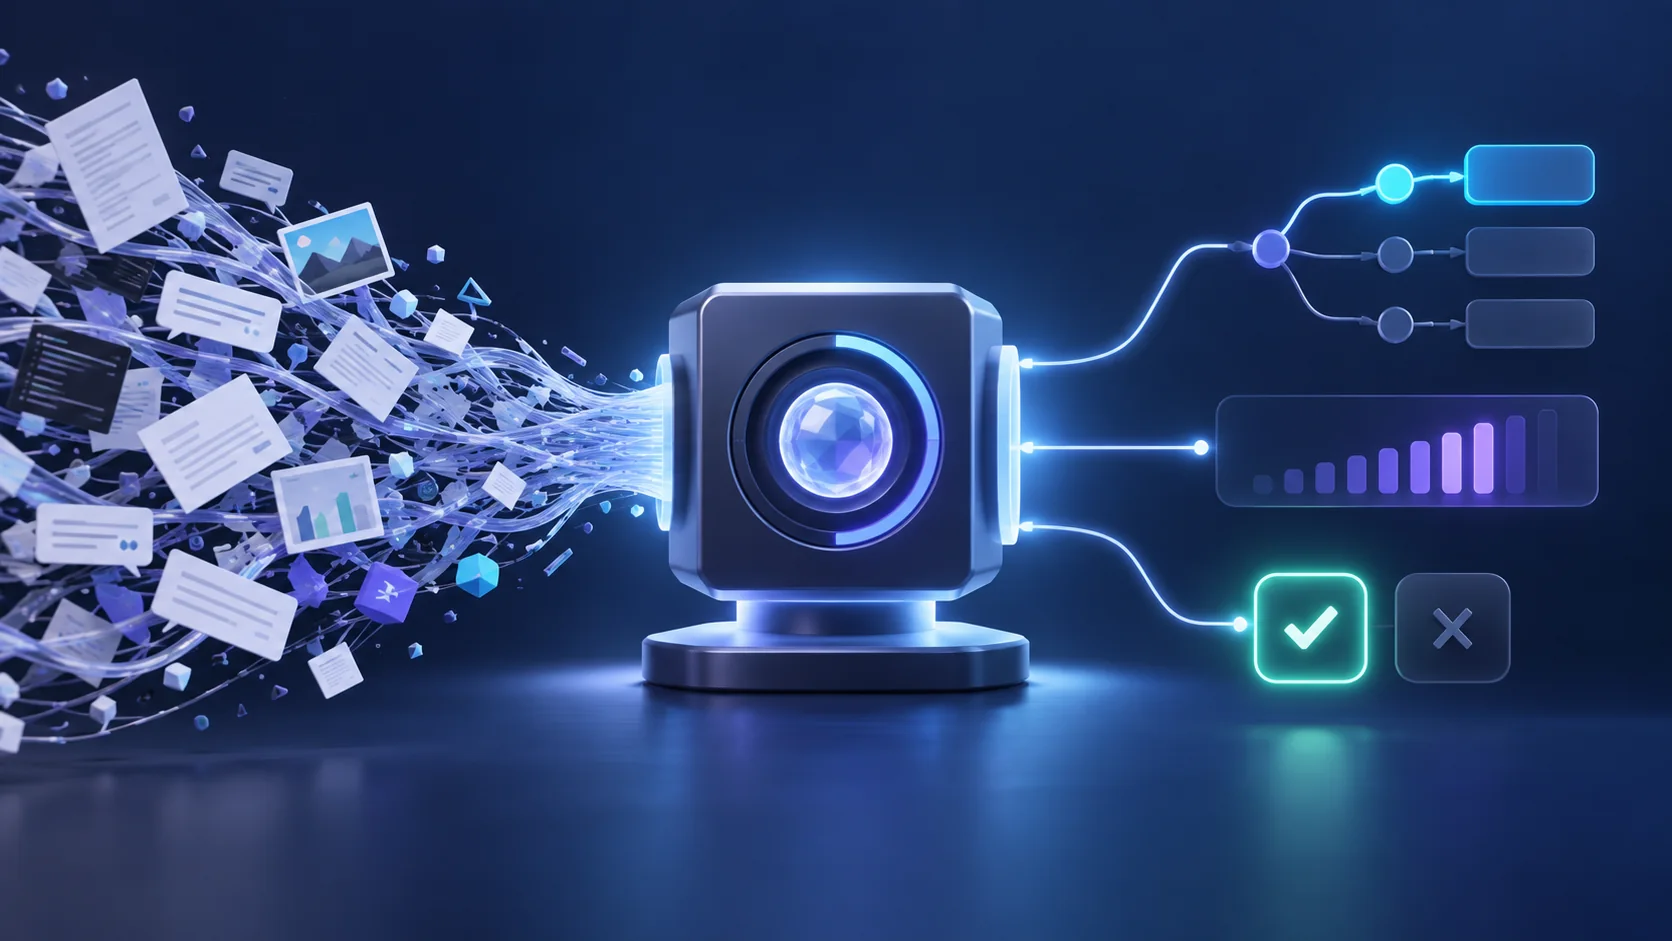
If you search for jev, you may see questions that sound as though it is another chatbot: What is Jev AI? Which Jev AI model should I choose? Can Jev write an answer, review a message, or power an agent? The useful starting point is simpler. Jev is a model for making bounded decisions about information you provide. You define the possible answers; Jev returns a structured judgment that software can use. For an open-ended explanation or a finished email, you still need a writing model or a person.
This guide separates the Jev model from the Jev AI website, explains the model names and three question types, and shows when a decision model earns its place beside a general-purpose large language model (LLM). You can explore the ideas in the Jev AI homepage Playground as you read.
What is Jev?
Jev is TypeSafe AI's first public System One model. In TypeSafe's terminology, System One models are built for quick, focused judgments that applications can consume directly. A Jev request contains a state—the text or structured facts to examine—and one or more typed questions. The response contains typed answers rather than a paragraph of generated prose. TypeSafe's introduction to Jev documents this request-and-answer design.
Consider a support message: “I was charged twice. Please return the second payment today.” A chat model might write a courteous reply. Jev can answer narrower questions about the same message: Which queue should receive it? Is a refund requested? How urgent is it on a scale your team defined? Those answers can feed a routing rule, a review screen, or a follow-up workflow. Jev makes the judgment; your application decides what happens next.
That distinction also clarifies the name Jev AI on this site. Jev AI is the website where you can learn the Jev approach, inspect examples, and use the homepage Playground. The Jev model itself is developed by TypeSafe. Our separate AI chat page serves conversational tasks and has its own model selector; a model appearing there depends on the currently available catalog.
Which Jev AI models are there?
Search phrases such as “Jev model AI,” “Jev LLM,” and “TypeSafe Jev AI” can make one product sound like several unrelated models. TypeSafe's current model reference names Jev 1.13, with the versioned ID jev-1.13.0. It also lists jev-latest and jev-preview as aliases. As of September 2026, both aliases point to that same version. An alias can move when a newer release appears; a versioned ID identifies a particular release.
| Name | What it means | When it matters |
|---|---|---|
jev-1.13.0 | A specific Jev release | Pin a tested version when repeatable behavior matters. |
jev-latest | The latest stable Jev alias | Follow the stable release as TypeSafe updates it. |
jev-preview | The newest Jev release alias, including previews when available | Evaluate a newer release before adopting it. |
These names describe version selection, not different skills such as “writing Jev” or “coding Jev.” The Jev AI homepage's own live decision endpoint currently requests Jev through a provider's jev-latest route; the exact upstream availability and returned version depend on that provider. If you see Choice, Score, or Noul in a tutorial, those are question types within a Jev request, not three more Jev models.
How does the Jev model make a decision?
Jev accepts a state and evaluates each question against it. State can be a customer note, article excerpt, policy text, or JSON-shaped record, provided the information is textual. A useful question names the condition being judged and defines the answer space. TypeSafe's primitives guide describes three forms:
- Choice selects from options you supply, such as Billing, Technical Support, or Other. The response includes the selected option, probabilities across the options, and a confidence value.
- Score places the state on an ordered rubric that you define, such as routine, time-sensitive, or blocking. It includes a score, probabilities across levels, and confidence.
- Noul gives the probability that a yes/no statement is true. “Does this customer explicitly request a refund?” is a Noul question. Noul does not have a separate confidence field.
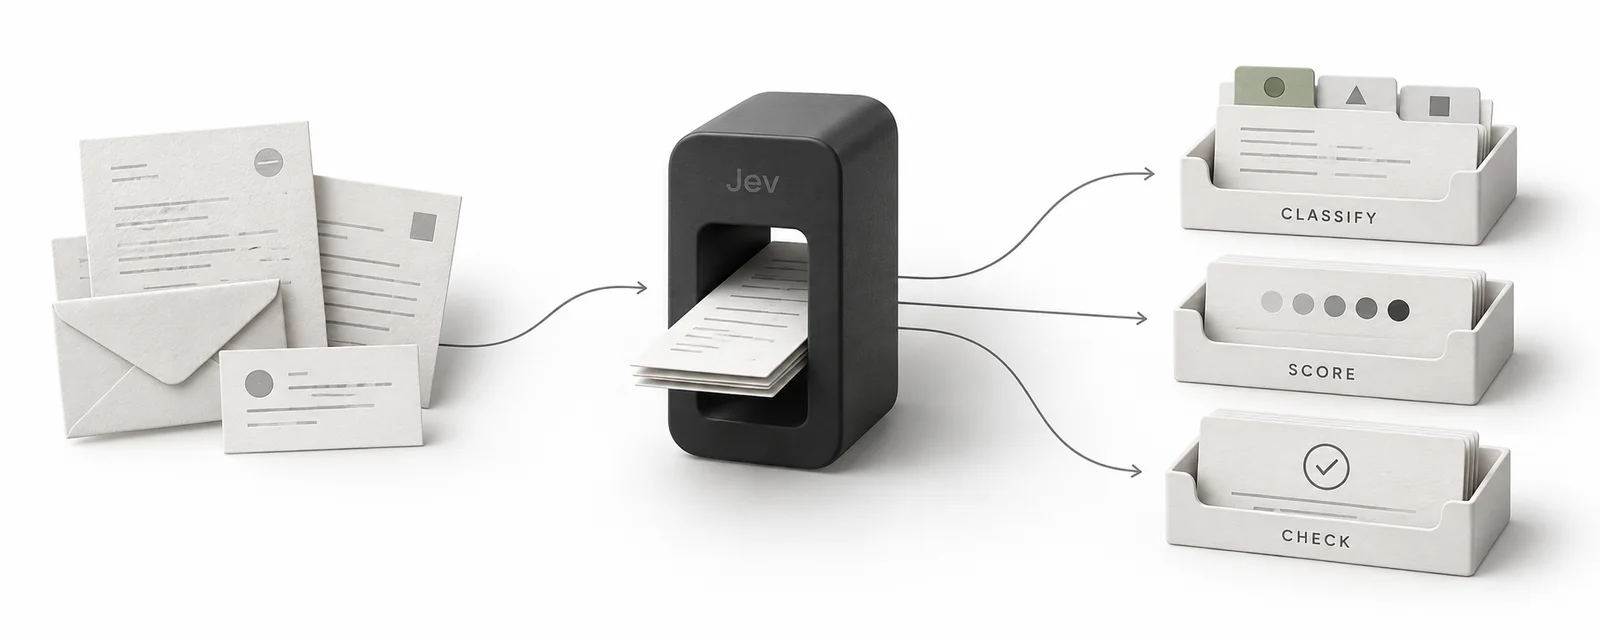
One request can contain several independent questions about the same state. For the duplicate-charge message, you might ask Choice for its queue, Noul for whether a refund was requested, and Score for urgency. The decision rules are yours: “urgent” should mean something observable, and an Other option helps when none of the named categories fits. Jev does not invent a new category outside the list you provided.
The probabilities are useful because a single label hides ambiguity. If Billing and General Support receive similar probabilities, a workflow can hold the ticket for review rather than treating the top label as certain. For Choice and Score, confidence summarizes how concentrated the probability distribution is; it is not a promise that the selected answer is correct. A Noul value near 0.5 similarly signals an uncertain yes/no judgment.
Jev versus an LLM: what changes?
The practical comparison is between a bounded decision and an open-ended response. General chat models such as GPT, Claude, and Gemini generate text token by token. They are useful when a person needs an explanation, a draft, a translation, or code ideas. Some can also produce JSON or follow a schema, but the application must still treat the generated content as a result to validate. Jev's answer space is defined before the request and its output has a fixed type.
| Task | Jev | General chat model |
|---|---|---|
| Route a ticket among known teams | A natural fit when teams and criteria are defined | Possible, but an extra text-generation step may be unnecessary. |
| Score a note against named levels | Returns a rubric-based position and uncertainty | Can discuss the rubric and explain a judgment in prose. |
| Draft a customer response | Cannot write the response | Designed to generate and revise the text. |
| Explain a complicated decision | Provides the bounded answers, not a narrative rationale | Can explain trade-offs using the supplied evidence. |
| Work with an image or audio file directly | Text-only input in the current Jev reference | Some chat models support those media, depending on the model. |
TypeSafe reports that Jev is fast and inexpensive for System One-shaped workloads, with parallel evaluation of questions. Those figures are vendor-reported, and a useful comparison must include the full workflow: preparation, network time, any follow-up LLM call, and the cost of reviewing mistakes. A Jev decision can be quicker than asking a large model to write a paragraph, but it does not replace the paragraph when one is actually needed.
A deterministic rule may be better still when the condition is exact, such as checking a numeric limit or matching a known account ID. A trained classifier can make sense when you already have a large labeled dataset and control its maintenance. Jev is most interesting in the middle: the answer is bounded, yet understanding the wording takes more than a simple rule.
Where does Jev work well—and where should you be careful?
Jev is well suited to repetitive decisions with clear options: support triage, content labeling, lead qualification, answer checks, or routing a request to the right handler. These tasks often have a high volume of small judgments and a measurable outcome. Start with one decision you can label by hand, write explicit criteria, and compare Jev's answers with your examples before automating anything.
Its boundaries matter just as much as its strengths. A type-safe answer can still be the wrong answer. If the state omits that a specialist already owns a customer case, Jev cannot reliably infer that hidden fact. If the options overlap, a confident choice may still disappoint your team. TypeSafe's own Jev 1.13 limitations note literal readings, numerical precision, date comparisons, and multi-step indirection as areas needing care. Keep arithmetic and hard rules in ordinary code; use the model where language judgment is needed.
For consequential decisions, measure error rates on your own cases and set a review path. A reasonable pattern is to accept routine, high-confidence classifications while sending uncertain or sensitive cases to a person. The right threshold depends on the cost of a mistake. Jev's uncertainty signal helps create that path; it does not eliminate testing or human accountability. For non-English workloads, TypeSafe says English currently performs best, so test the languages your users actually write.
Try Jev in the Jev AI homepage Playground
The easiest way to understand a decision model is to change the input while keeping the rules visible. Open the Jev AI homepage Playground, choose an example such as customer feedback or support tickets, and read the input beside its questions and answers. Switch to another input version to see which judgments change and which remain stable. These preset comparisons are editorial examples, so switching among them does not make a live model request.
To test your own text, choose Your own case in the Playground. Add a short input, then define a specific yes/no, Choice, or Score question. Where the live service is configured and available, Run Jev submits that case and shows the returned structured answer. Start with a low-stakes question such as “Does this note request a refund?” or “Which of these three teams should read it?” The full Jev AI examples provide more complete scenarios if you want to study how question wording changes a result.
This is also a useful way to compare Jev with a chat model on Jev AI. Ask Jev to classify a message, then use AI chat when you need to write the response. Put the same source facts in front of both, check each output against your goal, and keep the final action under your control.
Frequently asked questions about Jev
Is Jev an LLM or a chatbot?
Jev is a decision-focused AI model. It reads textual state and returns typed judgments, probabilities, and—on Choice and Score—confidence. It does not generate a free-form chat answer. Use a conversational model when you need written explanations, drafting, or back-and-forth discussion.
Are Jev, Jev AI, and TypeSafe AI the same thing?
No. TypeSafe AI develops the Jev model. Jev AI is this website's workspace for learning and trying AI tasks, including the homepage Jev Playground. The site also has a separate chat experience for general-purpose models. Checking the current model selector and Playground state tells you which live options are available here.
Can Jev be wrong if its output is type-safe?
Yes. Type-safe means the output fits the requested answer shape. Jev may still choose the wrong option or misjudge a yes/no statement. Add an Other option where appropriate, supply relevant context, test representative examples, and review decisions whose errors would matter.
Do I need an API key to use the Jev AI Playground?
The homepage examples are readable in your browser. The site's own live Jev option is presented through the Playground when its service is available; you do not enter a personal provider key in that interface. Availability and usage limits can change, so follow the information shown beside Run Jev before submitting a case.
Jev is easiest to appreciate when you give it a real, narrow judgment. Visit the Jev AI homepage Playground, compare one example, and then try a small case of your own. If the task calls for a full written answer, continue it with a chat model on Jev AI.
Keep exploring
 Model Comparisons
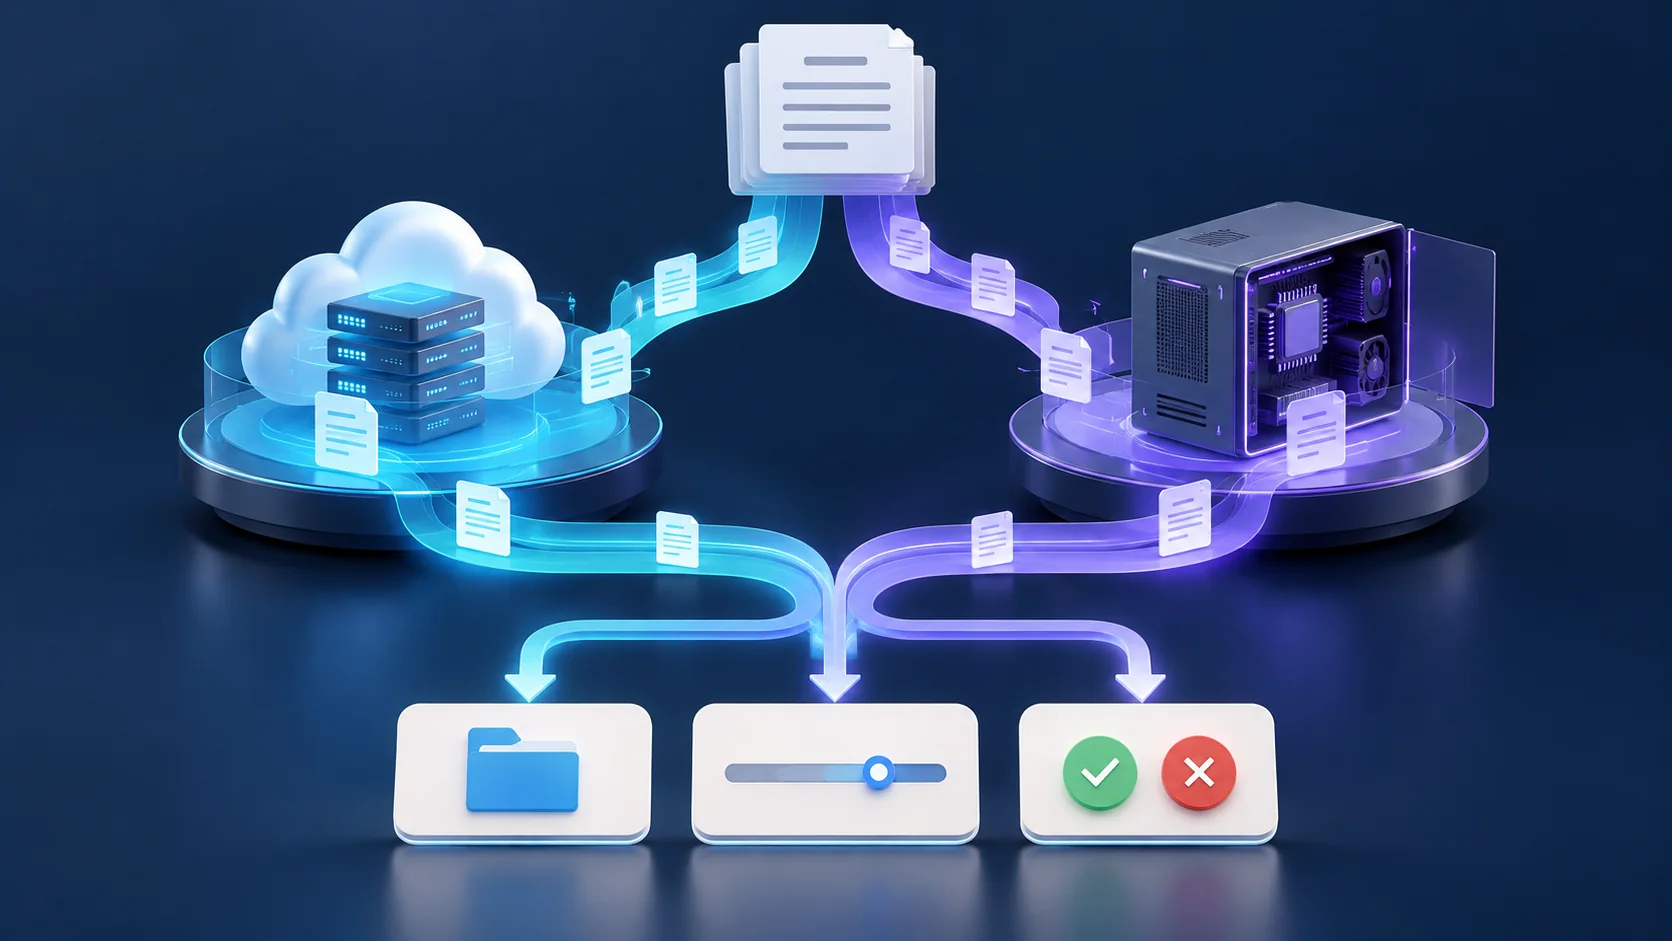
Jev vs Laya explained: compare typed outputs, open weights, context, benchmark results, and practical trade-offs. Explore Jev decisions in the Jev AI homepage Playground.
 Model Guides
What is OpenJev? Learn how this open-source decision server turns a state and typed questions into probabilities, how it differs from Jev, and what to test before using it.
Explore Jev AI
See a Jev decision in context.
Open the homepage Playground, compare an example, and turn your own text into a focused question when the live option is available.
Open the Jev AI Playground